Published 03.11.2026
Google, Microsoft, OpenAI and Anthropic have announced support for a shared robots.txt rule. It opts your site out of AI training and doesn't affect regular search. Not everyone honors it yet, so change your robots.txt with care.
The rule
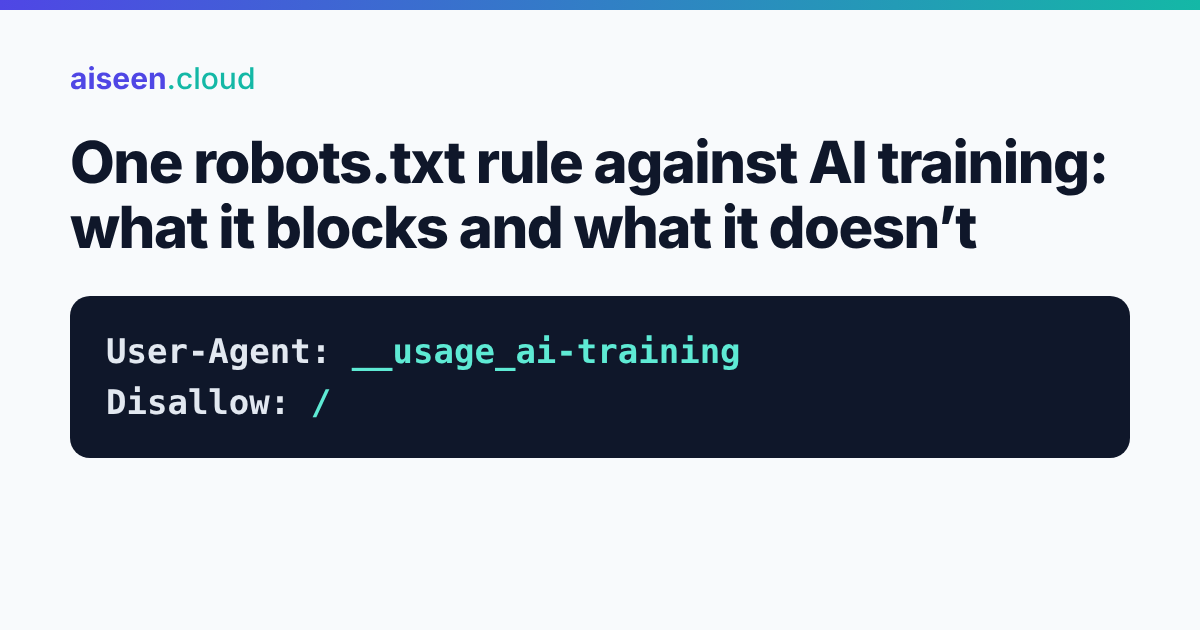
User-Agent: __usage_ai-training
Disallow: /
You can cover part of a site: Disallow: /articles/. Standard robots.txt path rules apply, and Microsoft also has a meta tag for individual pages.
The token is defined in an IETF draft dated October 30, 2026. It is an individual draft by an Anthropic employee, not an adopted standard, so it may still change.
When it takes effect
| Company | Timing |
|---|---|
| Microsoft | from February 1, 2027, as pages are crawled |
| planned for early 2027 | |
| OpenAI | in the coming months, no exact date |
| Anthropic | implementing now, support arriving over the coming months |
No other companies are on this list. Compliance is voluntary, and the rule doesn't apply to data already collected.
What the rule doesn't do
- It doesn't stop bots from visiting. It states how content may be used; it isn't a crawl block. To limit crawling, use rules for specific bots.
- It doesn't remove your site from AI answers. Answers and AI search are controlled separately. Microsoft, for example, has its own meta tag for answers:
<meta name="Bingbot" content="ai-grounding:disallow">. User-agent: *doesn't trigger it. A catch-all group doesn't count as a training opt-out: you must name the token.- It doesn't replace existing rules. Rules for GPTBot, ClaudeBot and Google-Extended still apply.
The Google catch
If you use the new token and don't mention Google-Extended, Google plans to treat that as disallowing Google-Extended too. That token isn't only about training: Google also links it to responses in the Gemini app. If appearing there matters to you, decide in advance and name Google-Extended explicitly. Check Google's documentation before you edit.
What to do now
Want to opt out of training but stay in AI answers? This setup works:
# Shared AI training opt-out
User-Agent: __usage_ai-training
Disallow: /

# Not everyone honors it yet, so keep the old blocks
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

# Leave AI search bots open
User-agent: OAI-SearchBot
Allow: /

User-agent: ChatGPT-User
Allow: /

User-agent: Claude-User
Allow: /

User-agent: PerplexityBot
Allow: /
If you don't mind training, change nothing: without this rule, no preference is expressed.
Check your site
The costliest mistake is blocking the wrong thing, such as search bots instead of training bots. The free aiseen.cloud check shows in 15 seconds which bots your site lets in.
Sources: Google, Microsoft, OpenAI, Anthropic on the IETF list, IETF draft.